

An AI assistant returns a normal-looking answer. Behind that answer, a tool may have accessed a file, contacted a service, or changed application state.
That makes the conversation an incomplete place to assess security.
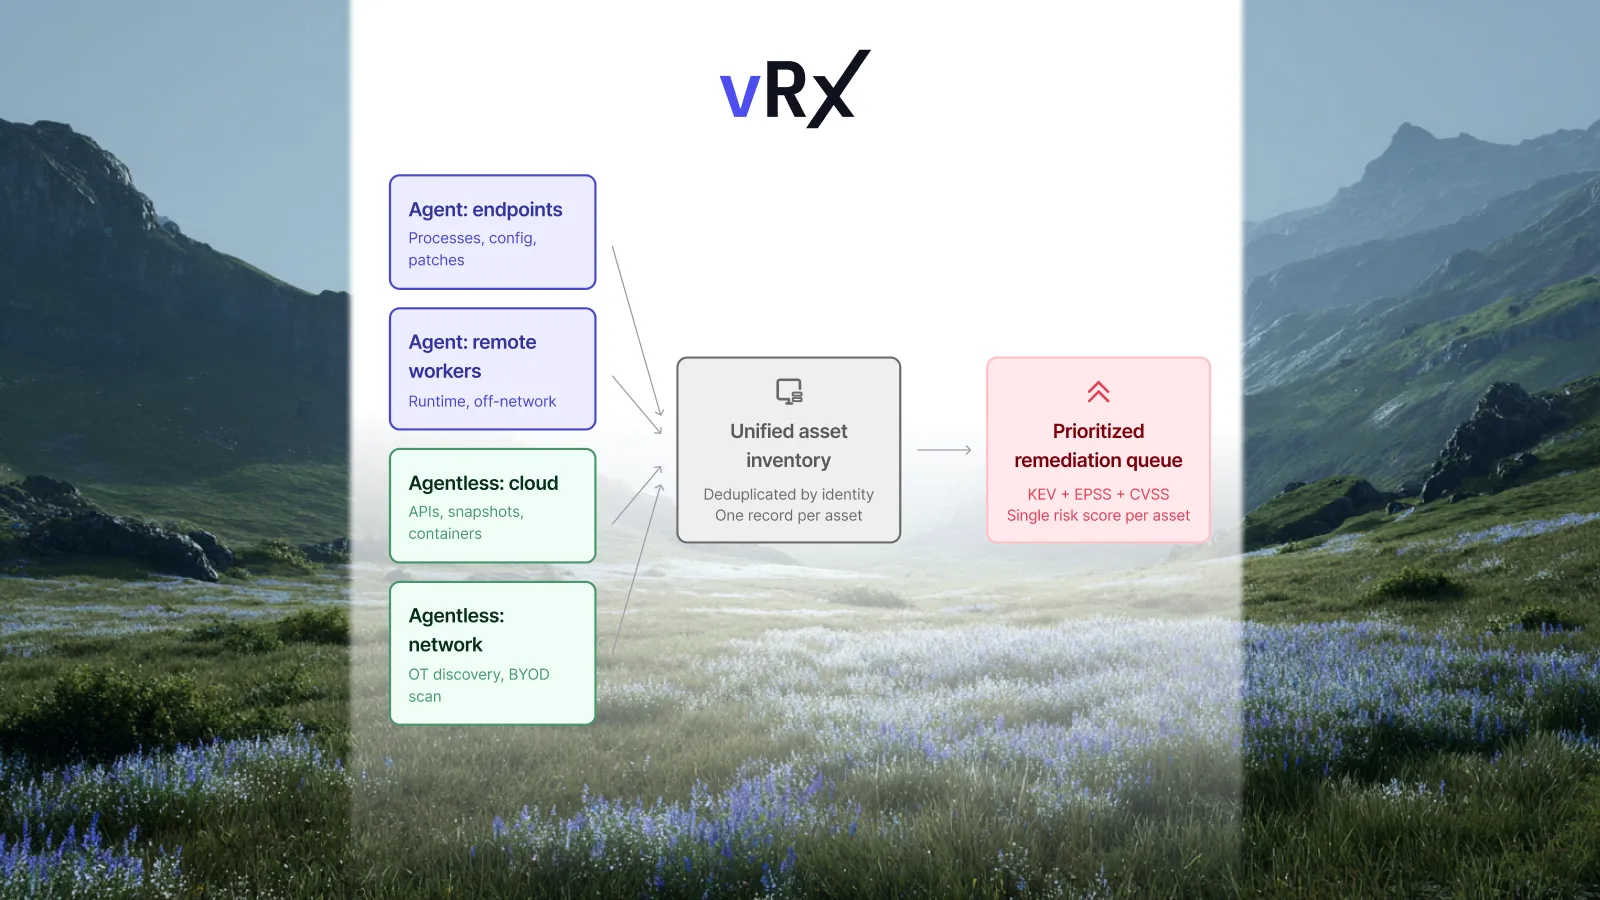
MCP security requires protecting the software, permissions, and data flows connecting an AI application to its tools. When a dependency has a known vulnerability, the investigation should establish where it runs, whether the affected behavior is accessible, what consequences are possible, and which action addresses them.
A package finding starts that investigation. A clean-looking response does not close it.
What is MCP security?
Model Context Protocol, or MCP, provides a common way for AI applications to connect to external capabilities and information.
Its architecture distinguishes the host application, clients that maintain connections, and servers that expose capabilities. A server may run locally or remotely. The security review needs to identify the actual deployment rather than assume every MCP integration has the same execution model. MCP architecture overview.
For a security team, the practical scope includes:
• The source and integrity of the server software.
• Dependencies in the deployed runtime.
• Authentication and authorization.
• Files, credentials, services, and network destinations available to tools.
• How returned information is handled by the host.
• Approval and verification of consequential actions.
A server’s description explains its intended purpose. The review must establish what its implementation and permissions allow.
For example, a document-search tool might need to read one approved repository. That does not, by itself, justify access to every directory or credential available to the account running it.
Start with the security controls that apply to your deployment
Dependency analysis belongs alongside access controls, not in place of them.
The official MCP security guidance addresses risks including confused-deputy behavior, token passthrough, and local server execution. It prohibits token passthrough and recommends restricted, sandboxed execution for local servers, with limited filesystem and network access. MCP security best practices.
Translate those principles into deployment-specific checks:
| Area | Question for the owner | Evidence to request |
|---|---|---|
| Server identity | Which implementation are we running, and where did it come from? | Repository or supplier, release, artifact identity, and deployment owner |
| Authorization | Which user or service identity authorizes this operation? | Relevant permission configuration and authorization tests |
| Local execution | What can the server process access? | Execution account, mounted directories, available credentials, and isolation settings |
| Remote access | Which destinations and operations are permitted? | Endpoint inventory, access policy, and relevant request records |
| Dependencies | Which affected component is present in the running deployment? | Resolved package version, image or environment identity, and advisory |
| Verification | What evidence would demonstrate that the problem is addressed? | Explicit acceptance criteria and a named reviewer |
This is a recommended review worksheet, not an MCP certification checklist.
Keep the answers tied to a specific environment. A developer’s restricted test setup does not establish the permissions of a shared production deployment.
What recent research found
An October 4, 2026 preprint, Characterizing Security Effects of OSS Vulnerabilities in Agent Systems, examined how known open-source software vulnerabilities manifest in agent executions.
In its real-world evaluation across five agent hosts, the researchers retained 25 reachable vulnerability instances. Their Oscar analysis identified realized effects in nine cases. Five reached model-visible observations; four remained at runtime.
The remaining cases included both executions without an established attributable effect and cases with insufficient evidence. They cannot all be labeled harmless.
The study distinguishes dependency presence, reachability, realized effects, and how far those effects propagate. Its results concern selected tasks, inputs, and configurations, not the prevalence of exploitation across MCP deployments. Research paper, evaluation and discussion.
For practitioners, this raises an important review question: does the evidence cover the underlying operation, or only the message returned afterward?
How to investigate a vulnerable MCP dependency
The workflow below is a recommended operating method. It is intended for authorized investigation and validation, not testing third-party systems without permission.
1. Locate the affected component in the running system
Begin with the advisory and the deployed artifact.
Record the package, version, dependency path, server or host using it, and environment identifier. Establish whether the component is a direct dependency, a transitive dependency, or part of another service the tool calls.
Keep repository evidence separate from deployment evidence. A corrected dependency file does not demonstrate that every running instance was rebuilt and replaced.
Assign an owner who can make the relevant change. An application team may own the host while another team operates a remote MCP server. The ticket should identify the boundary between them.
2. Define the behavior that matters
Translate the advisory into a concrete assessment question.
Depending on the vulnerability, that might concern an unauthorized read, an unintended write, incorrect credential handling, or a request sent to an unintended destination.
Record the conditions the advisory describes. Then identify the relevant tool operation, input handling, and permissions in your deployment.
Do not require a working exploit before taking a supported security update. Detailed investigation should help resolve uncertainty or choose an immediate response. It should not become a reason to postpone a straightforward fix.
3. Examine the operation as well as its response
Choose evidence that can answer the assessment question.
If the concern is an unintended file change, inspect the relevant filesystem state. If it is credential exposure, investigate the applicable request path using safe test credentials. If it is an authorization failure, examine the identity and permission decision associated with the operation.
Retain tool responses and host records where useful, but avoid making the chat transcript the only evidence source.
Use synthetic data in a controlled environment wherever possible. Do not copy production secrets into a test merely to make it realistic.
Also record visibility limits. Missing logs or unavailable instrumentation should appear as an unresolved part of the assessment, not disappear into a confident conclusion.
4. Select a response that addresses the affected behavior
A supported update may be the clearest permanent fix. Other immediate options can include disabling the affected tool, restricting a relevant permission, removing an unnecessary integration, or narrowing access to a specific resource.
Evaluate each option against the actual scenario.
For example, restricting outbound network access would not, by itself, address every unauthorized local file modification. Removing a tool from the model’s available choices also needs verification that the affected operation is no longer accessible through the remaining application paths.
Document whether the action is a permanent correction or a temporary mitigation. Temporary controls need an owner, review date, and outstanding remediation task.
5. Verify the deployed change and preserve the result
Write acceptance criteria before applying the change.
The record should identify the corrected deployment, the security condition being checked, and the legitimate workflow that must continue to work.
For a package update, confirm the active version or artifact, then perform the appropriate validation. For a permission change, verify the intended restriction and check that required access still works.
The patch verification checklist provides supporting guidance for the update portion of this process. MCP-specific validation should also account for the tool’s permissions and operational behavior.
A worked example: a document tool with excessive filesystem access
Consider a hypothetical internal assistant that summarizes documents through a locally running MCP server.
The server uses a document-processing dependency covered by a security advisory. It runs under an account with access to both the approved document directory and an unrelated project directory.
The team first confirms that the affected version is present in the deployed environment. It then reviews the advisory against the tool’s supported inputs and how the dependency is called.
In an authorized test environment, engineers use synthetic files and check both the response and the relevant filesystem state. Suppose the test reveals an unintended modification outside the approved document directory, while the assistant still returns an ordinary summary.
The response alone would have missed the condition the team needed to investigate.
An appropriate remediation record could include:
• The affected server build and dependency version.
• The advisory and assessed operation.
• The unexpected file change observed in the test.
• An immediate restriction on unnecessary directory access.
• The supported dependency update or replacement.
• Post-change checks covering both the file boundary and normal document processing.
This example is illustrative, not a reported incident or a claim about every document-processing tool.
Its purpose is to make the acceptance criteria concrete: successful summarization and correct filesystem behavior are separate requirements.
Do not confuse dependency vulnerabilities with prompt injection
These problems can interact, but they require different investigation questions.
A dependency vulnerability concerns software behavior under particular conditions. Prompt injection concerns untrusted content influencing an AI system’s instructions or actions. Fixing one does not establish that the other has been addressed.
For this review, keep two separate records:
1. Whether the software operation respects its intended security boundary.
2. Whether information returned to the host is handled with the appropriate level of trust.
A result can be relevant to the user’s task without being authoritative. Retrieved text should not gain permission to change the workflow simply because it arrived through an approved tool.
For the source-trust side of this problem, see Grounded does not mean trusted: securing AI-assisted remediation. That is a complementary concern, not a substitute for dependency remediation.
What should an MCP security ticket contain?
A useful ticket should let the next engineer understand the decision without replaying the whole investigation.
Include the affected deployment and owner, the advisory, the relevant operation, available evidence, and any unresolved questions. State the selected response and its acceptance criteria.
Use precise status language:
• Affected component confirmed: the relevant package or implementation is present.
• Impact under investigation: the team has not completed the deployment-specific assessment.
• Mitigation verified: a defined temporary control passed its agreed checks.
• Fix verified: the corrective change is active and the closure criteria were met.
These are suggested workflow labels. Adapt them to your organization’s process.
Avoid “safe” as a catch-all conclusion. A narrow test may justify a narrow statement, such as “the assessed operation was blocked under this configuration.” It does not establish that every input, identity, or execution path is secure.
Frequently asked questions
Does using MCP make an AI application insecure?
MCP is an integration protocol, not a guarantee of either security or insecurity. Assess the implementation, deployment, permissions, connected services, and handling of untrusted data. Local and remote servers require different operational checks. MCP architecture.
Is dependency scanning enough for MCP security?
No. Dependency scanning helps identify known affected components. The review also needs to establish where those components run, what access the tools have, and how corrective changes will be verified. Keep scanning as a baseline rather than treating it as the entire assessment.
Can a normal model response prove that a tool operation was safe?
No. The response is only one observation. For the method proposed here, verification should inspect the relevant resource or security condition directly, such as an authorization decision, file change, or outbound request. A normal answer is not a general-purpose security test.
Should teams wait for a demonstrated impact before updating?
Not automatically. When a supported fix is available and applicable, follow the organization’s remediation requirements. Use additional investigation to resolve uncertainty and inform priority or mitigation, not as a universal prerequisite for installing security updates.
How should teams handle a fix that cannot be deployed immediately?
Choose a relevant temporary restriction, verify its intended effect, and record what remains exposed or uncertain. Options may include disabling the affected operation or reducing its permissions. Give the exception an owner and review date, and keep the permanent fix visible.
Review one MCP workflow from deployment to verification
Choose one MCP integration your organization already uses.
Identify its owner, deployed software, available permissions, and one important operation. Then write the evidence you would need to investigate a dependency advisory and confirm a fix.
If the answer ends at “the assistant returned the expected response,” extend the review to the resource or operation that actually needs protection.